
Speculative Decoding Deep Dive II: Medusa, MTP
Created on August 15, 2026
Three ways to produce the draft: a separate small model (classic), extra heads on the target (Medusa), or heads baked in during pretraining (MTP).
Classic solution
A small autoregressive model proposes ; the target verifies all four in one forward (~2–3x). The original recipe (Leviathan et al., 2023; Chen et al., 2023) needs no extra training: draft with a smaller same-family model so and share tokens and context.
- Same tokenizer — else and aren't over the same .
- Same chat template — a format mismatch is a context mismatch: .
- Same architecture / pretraining — so ; a random small model gets .
If none exists, distill or fine-tune the draft (DistillSpec). Medusa and MTP drop the separate model.
The draft is autoregressive, so cost grows with speculated length :
Draft 1: upside near . Draft 32: slow, and the tail is usually wrong. A few tokens is the structural limit.
Medusa
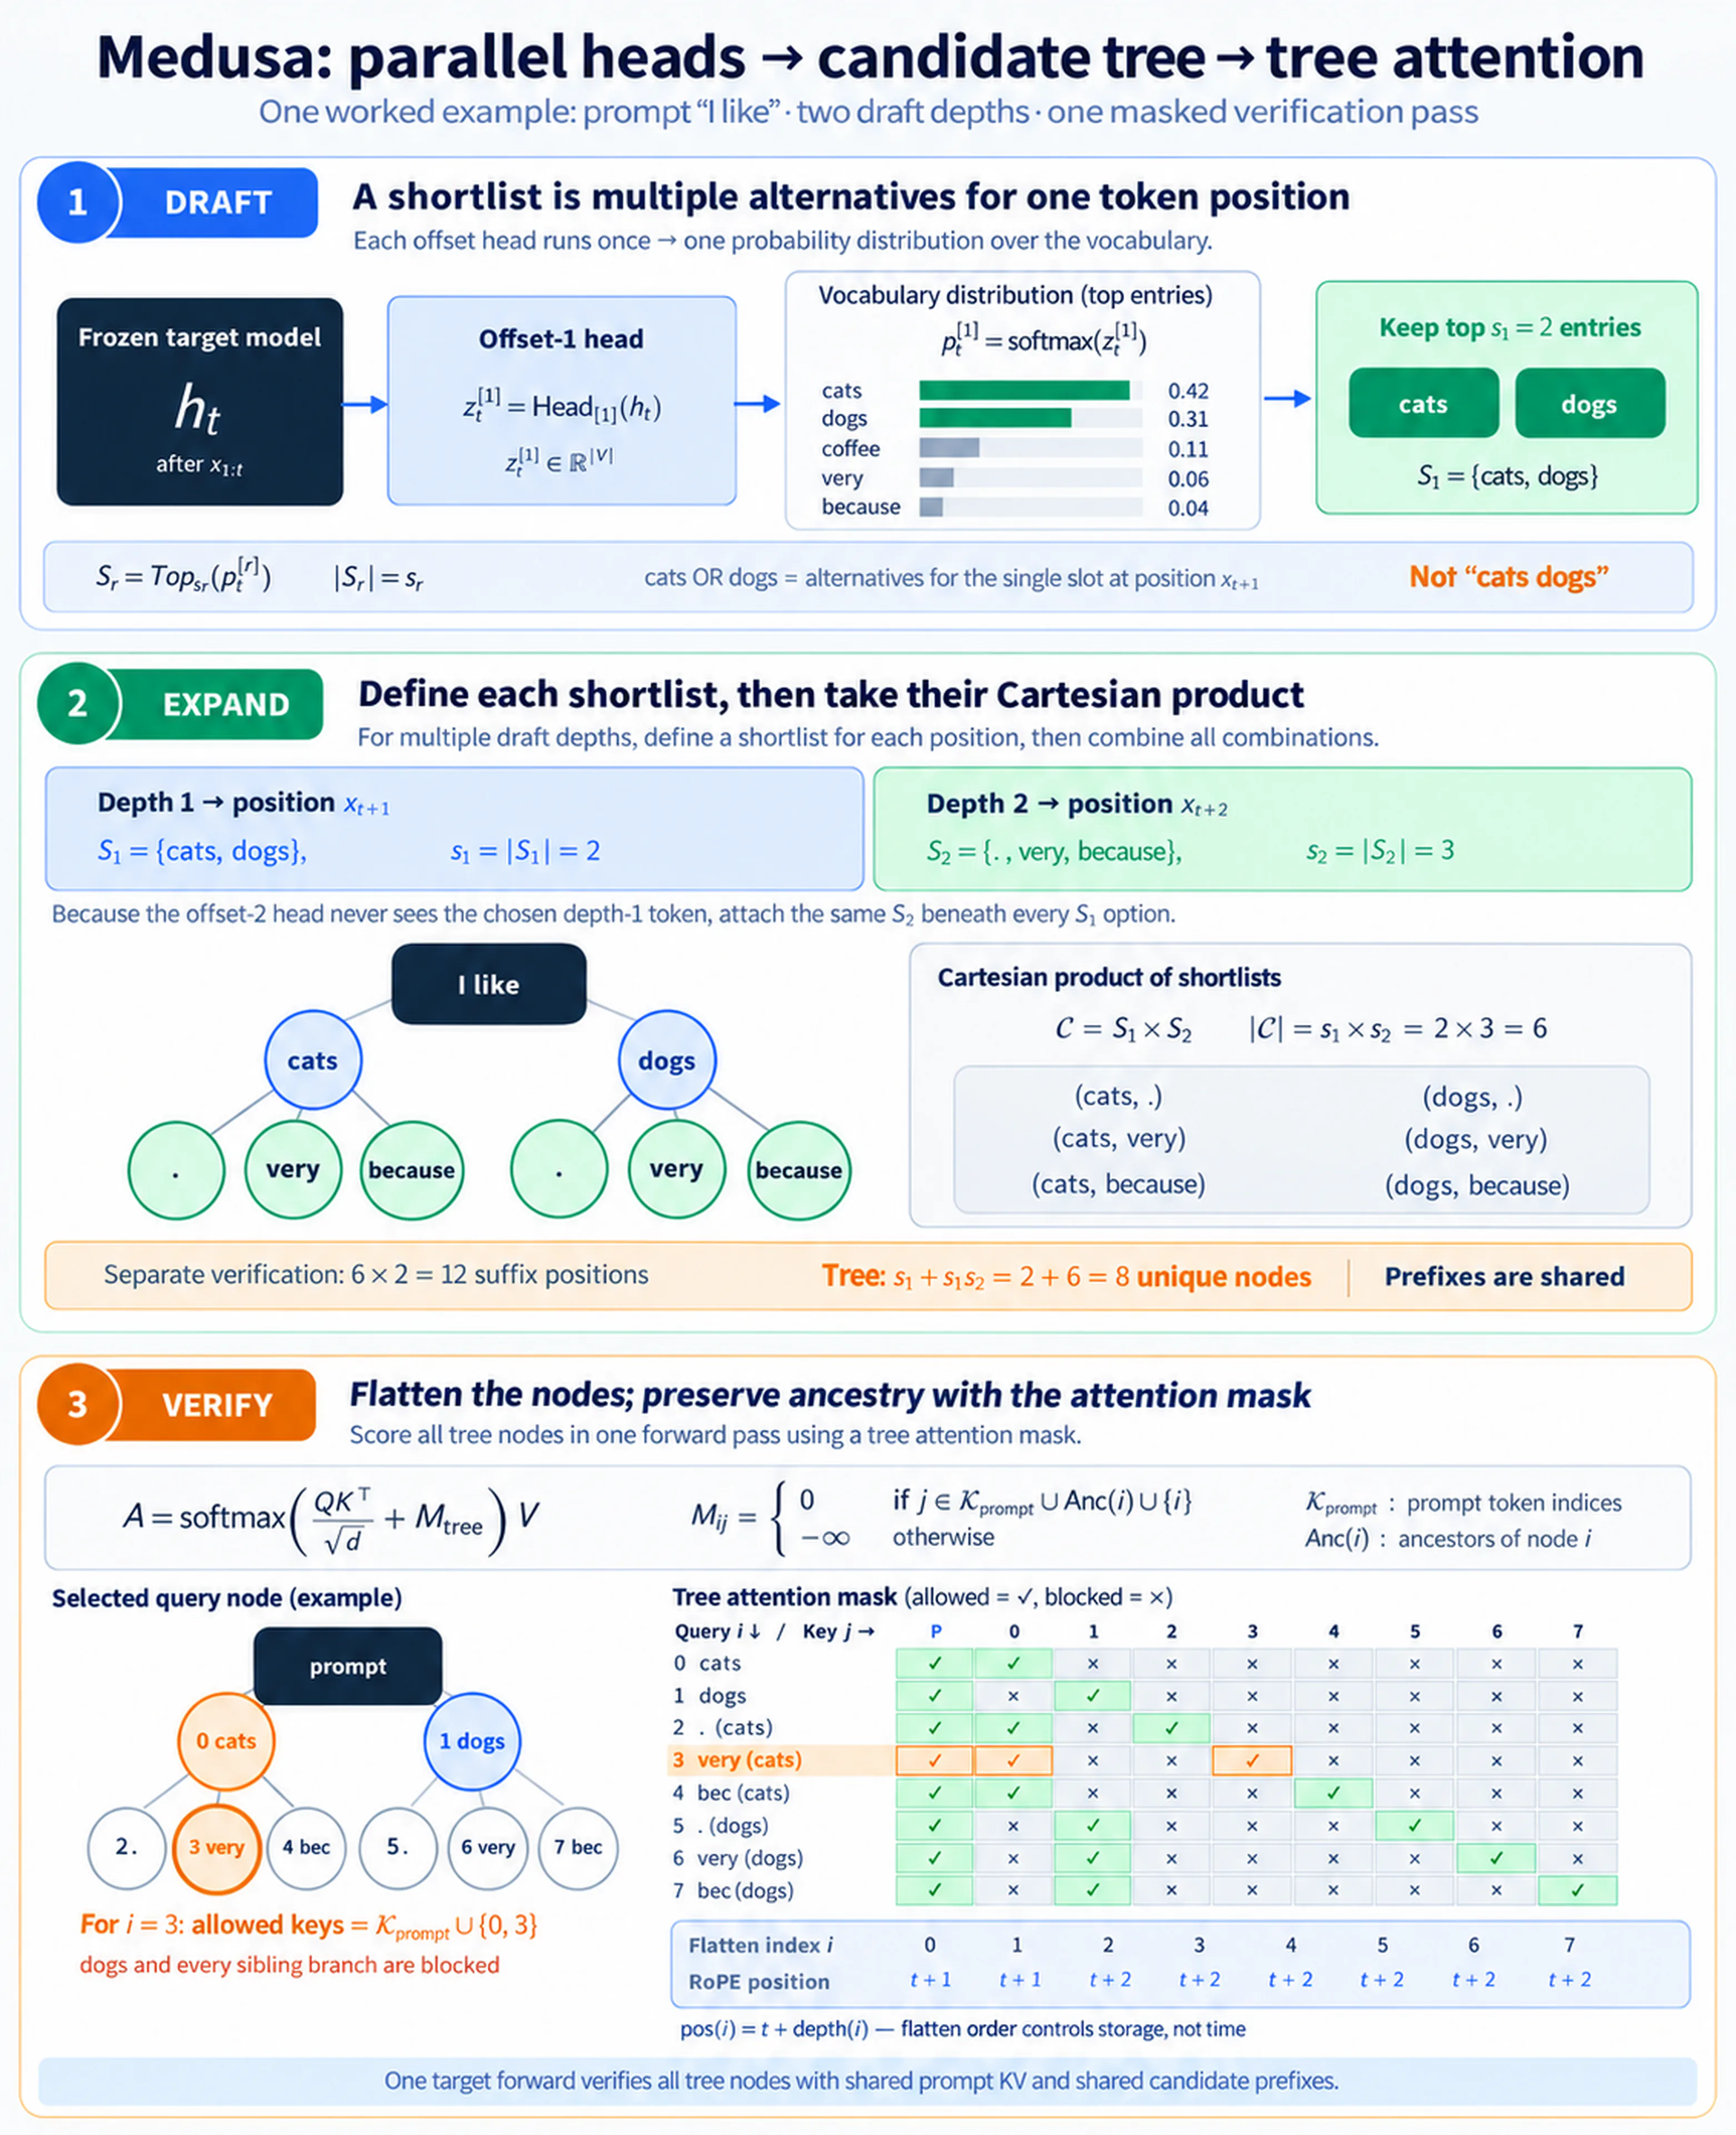
Medusa (Cai et al., 2024) freezes the target and adds heads on . The figure is the pipeline: draft → expand → verify. = ancestors of node on that tree. For shortlist sizes :
- full paths — (what you would verify as separate sequences)
- tree nodes — (each depth adds one product term)
Heads never see the token just sampled, so accuracy falls with offset (suffix decay). Hydra (Ankner et al., 2024) feeds to later heads — better drafts, less parallelism.
Training. Supervise head with the token steps past Head 0's target, :
- Medusa-1 — freeze the model, train only heads . ~2.2x.
- Medusa-2 — also fine-tune the trunk so adapts. ~2.3–3.6x, accepted length ~3.0–3.5.
MTP
Multi-token prediction (Gloeckle et al., 2024) uses the same architecture: shared trunk, parallel heads on , one shared unembedding .
Two differences: the heads are transformer layers (not a single MLP), and they are a pretraining objective — every position is trained on all next tokens:
Aim is sample efficiency and better representations; faster decoding (~3x, extra heads + Medusa-style tree attention) is a by-product.
| Medusa | MTP | |
|---|---|---|
| Heads | one MLP, added after training | transformer layers, present in pretraining |
| Trunk | frozen (Medusa-1) | trained under |
| Purpose | speed | representations; speed is a bonus |
EAGLE keeps a sequential draft but conditions each step on the token actually sampled — the branch information Medusa-style heads never get.
References
- Cai et al., 2024. Medusa: Simple LLM Inference Acceleration Framework with Multiple Decoding Heads. arXiv 2401.10774
- Gloeckle et al., 2024. Better & Faster Large Language Models via Multi-token Prediction. arXiv 2404.19737
- Ankner et al., 2024. Hydra: Sequentially-Dependent Draft Heads for Medusa Decoding. arXiv 2402.05109


